RoXDrive: Closed-Loop Reinforcement Learning for End-to-End Autonomous Driving via Action-Faithful Rollouts
RoXDrive Demo
For efficient web delivery, these videos use the compressed versions.
Qualitative Visualization
nuScenes
Public nuScenes · Original vs RoXDrive.
Avoid Collision
Original official weights vs RoXDrive · 4 s
In-House Driving Data
Closed-loop comparisons across challenging in-house driving scenes.
Collision Avoidance
Safe responses to dynamic obstacles and collision risks.
Avoid Collision
Original policy vs RL post-training · 6 synchronized views
Keep in Drivable Area
Lane-boundary awareness and recovery within the drivable region.
Keep in Drivable Area
Original policy vs RL post-training · 6 synchronized views
TL;DR
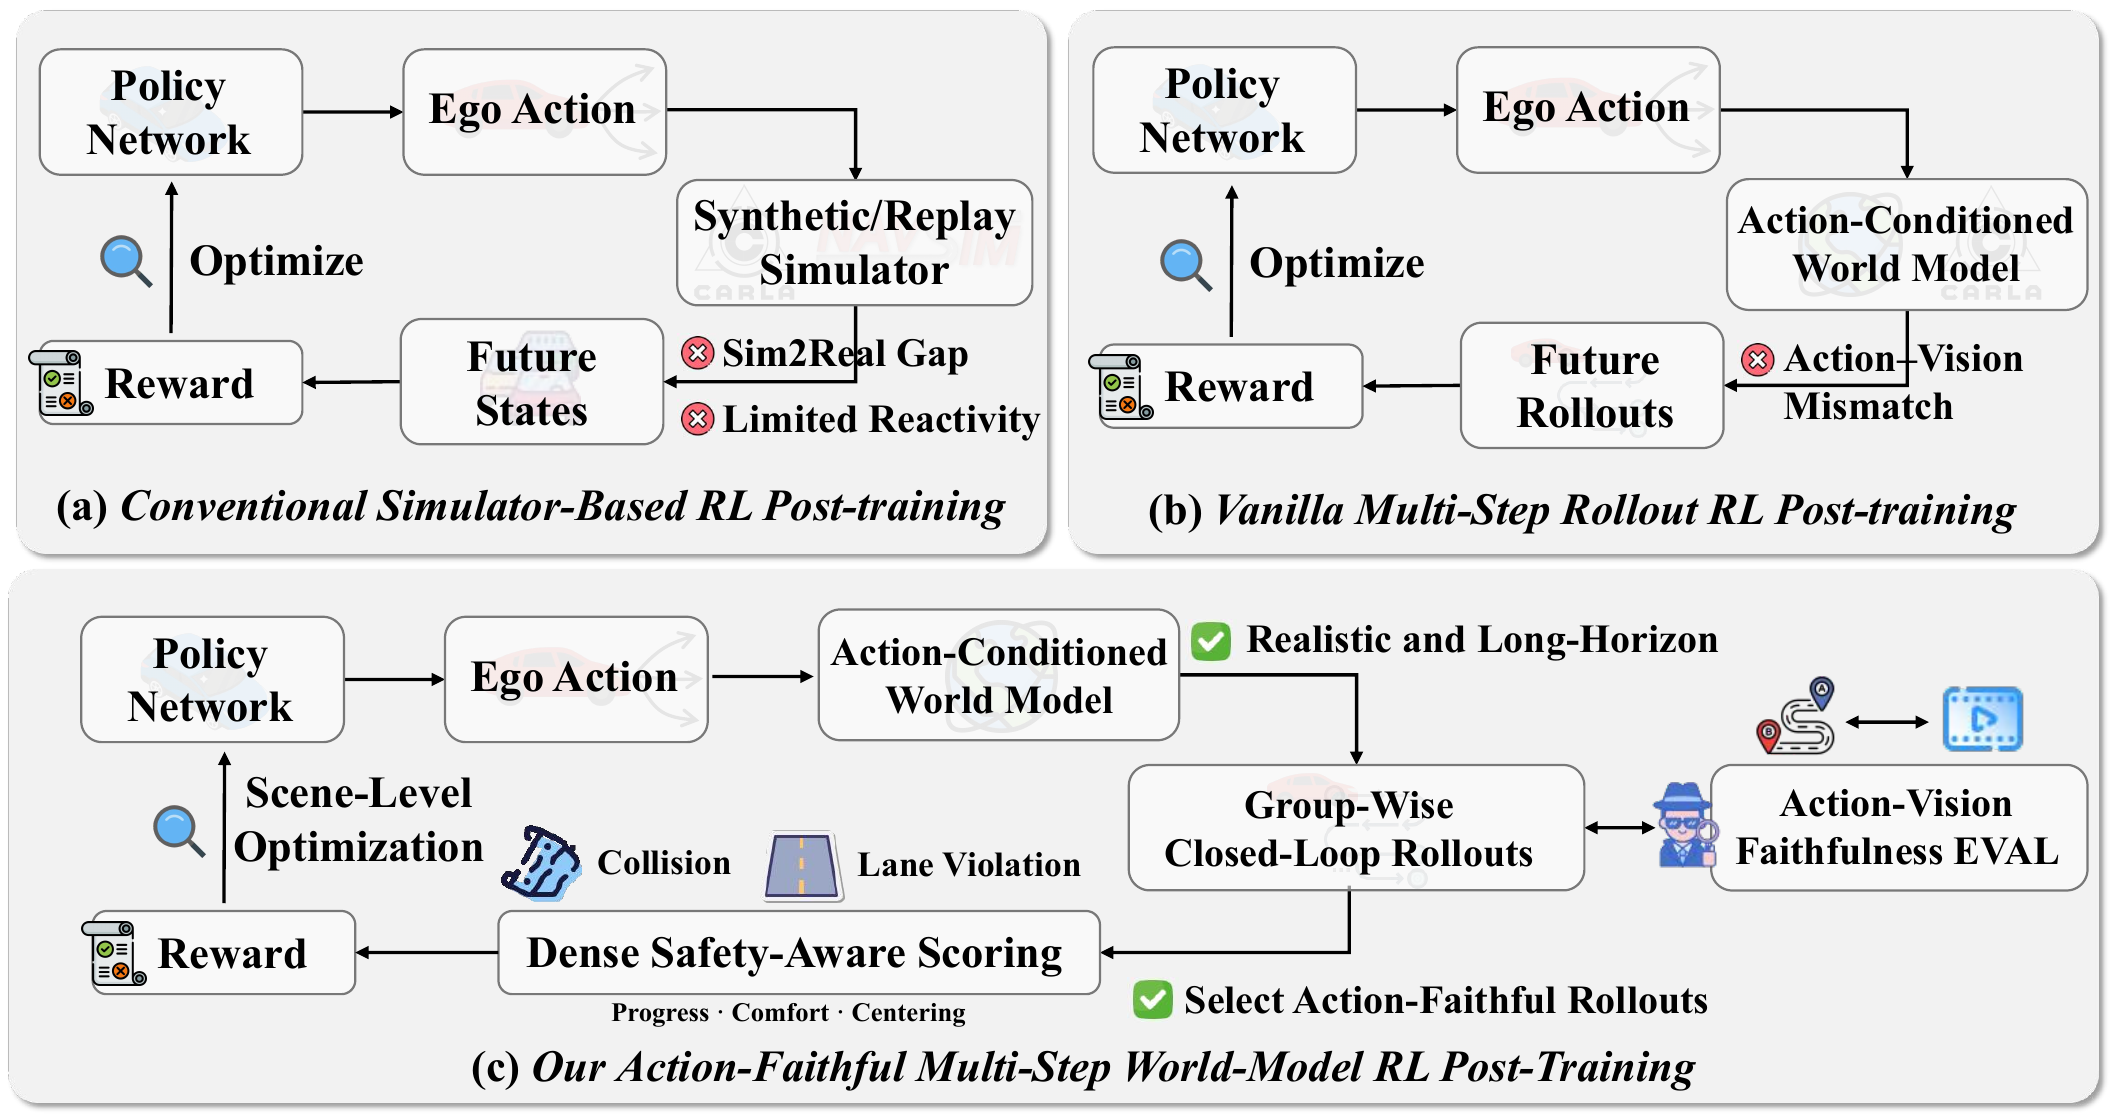
We introduce RoXDrive, a plug-and-play closed-loop RL framework that enables reliable policy optimization through action-faithful world-model rollouts. RoXDrive consists of two stages:
- 1
Model pre-training
Alongside imitation pre-training, the Action-Vision Faithfulness Evaluator uses geometry-aware trajectory supervision to verify long-horizon action-vision consistency.
- 2
Action-faithful RL post-training
With a fixed world model, only action-faithful long-horizon rollouts receive dense safety-aware scoring for scene-level closed-loop RL.
Motivation
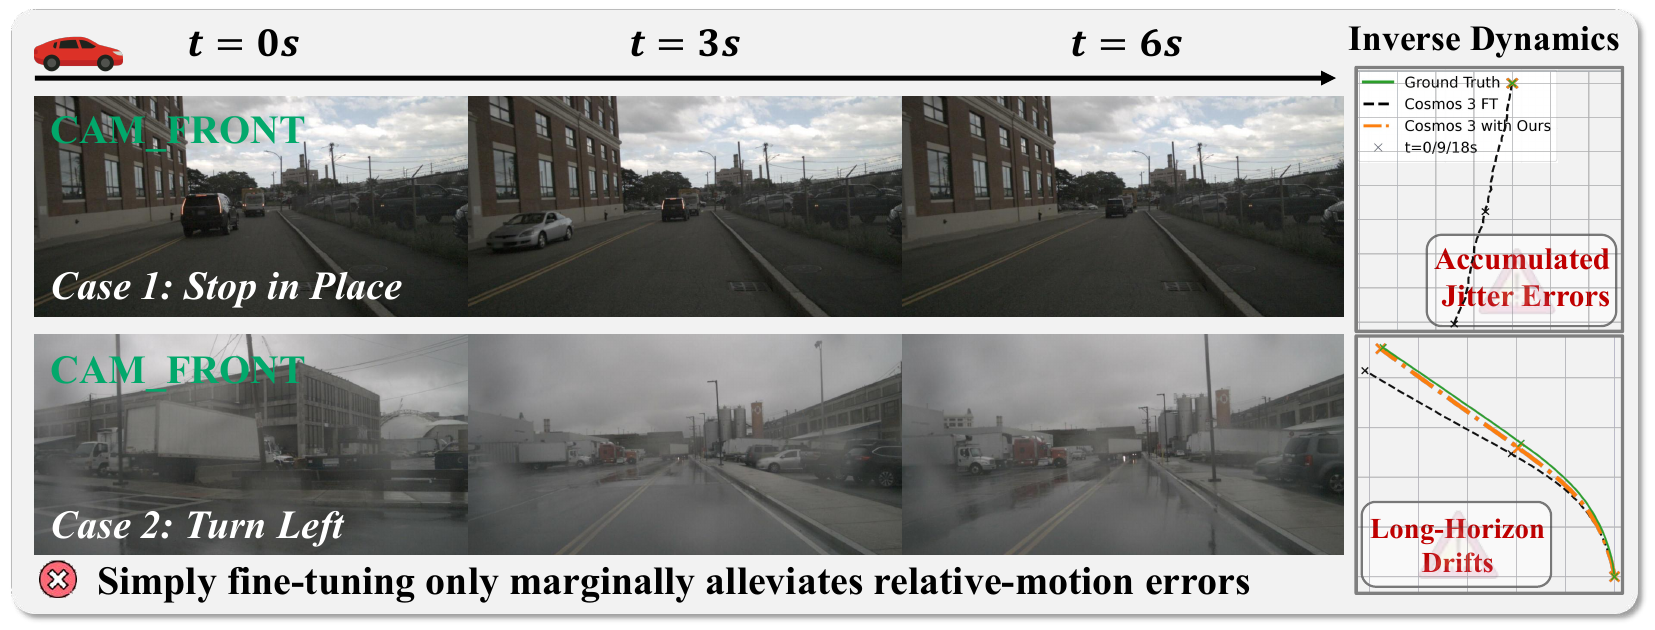
Video world models are promising scalable simulators for closed-loop policy learning, but visual realism alone does not guarantee that future observations causally follow the policy's ego actions.
Fine-tuning only marginally reduces relative-motion errors; small inverse-dynamics inaccuracies still accumulate into jitter and long-horizon drift, making rollouts unreliable for policy optimization.
Method
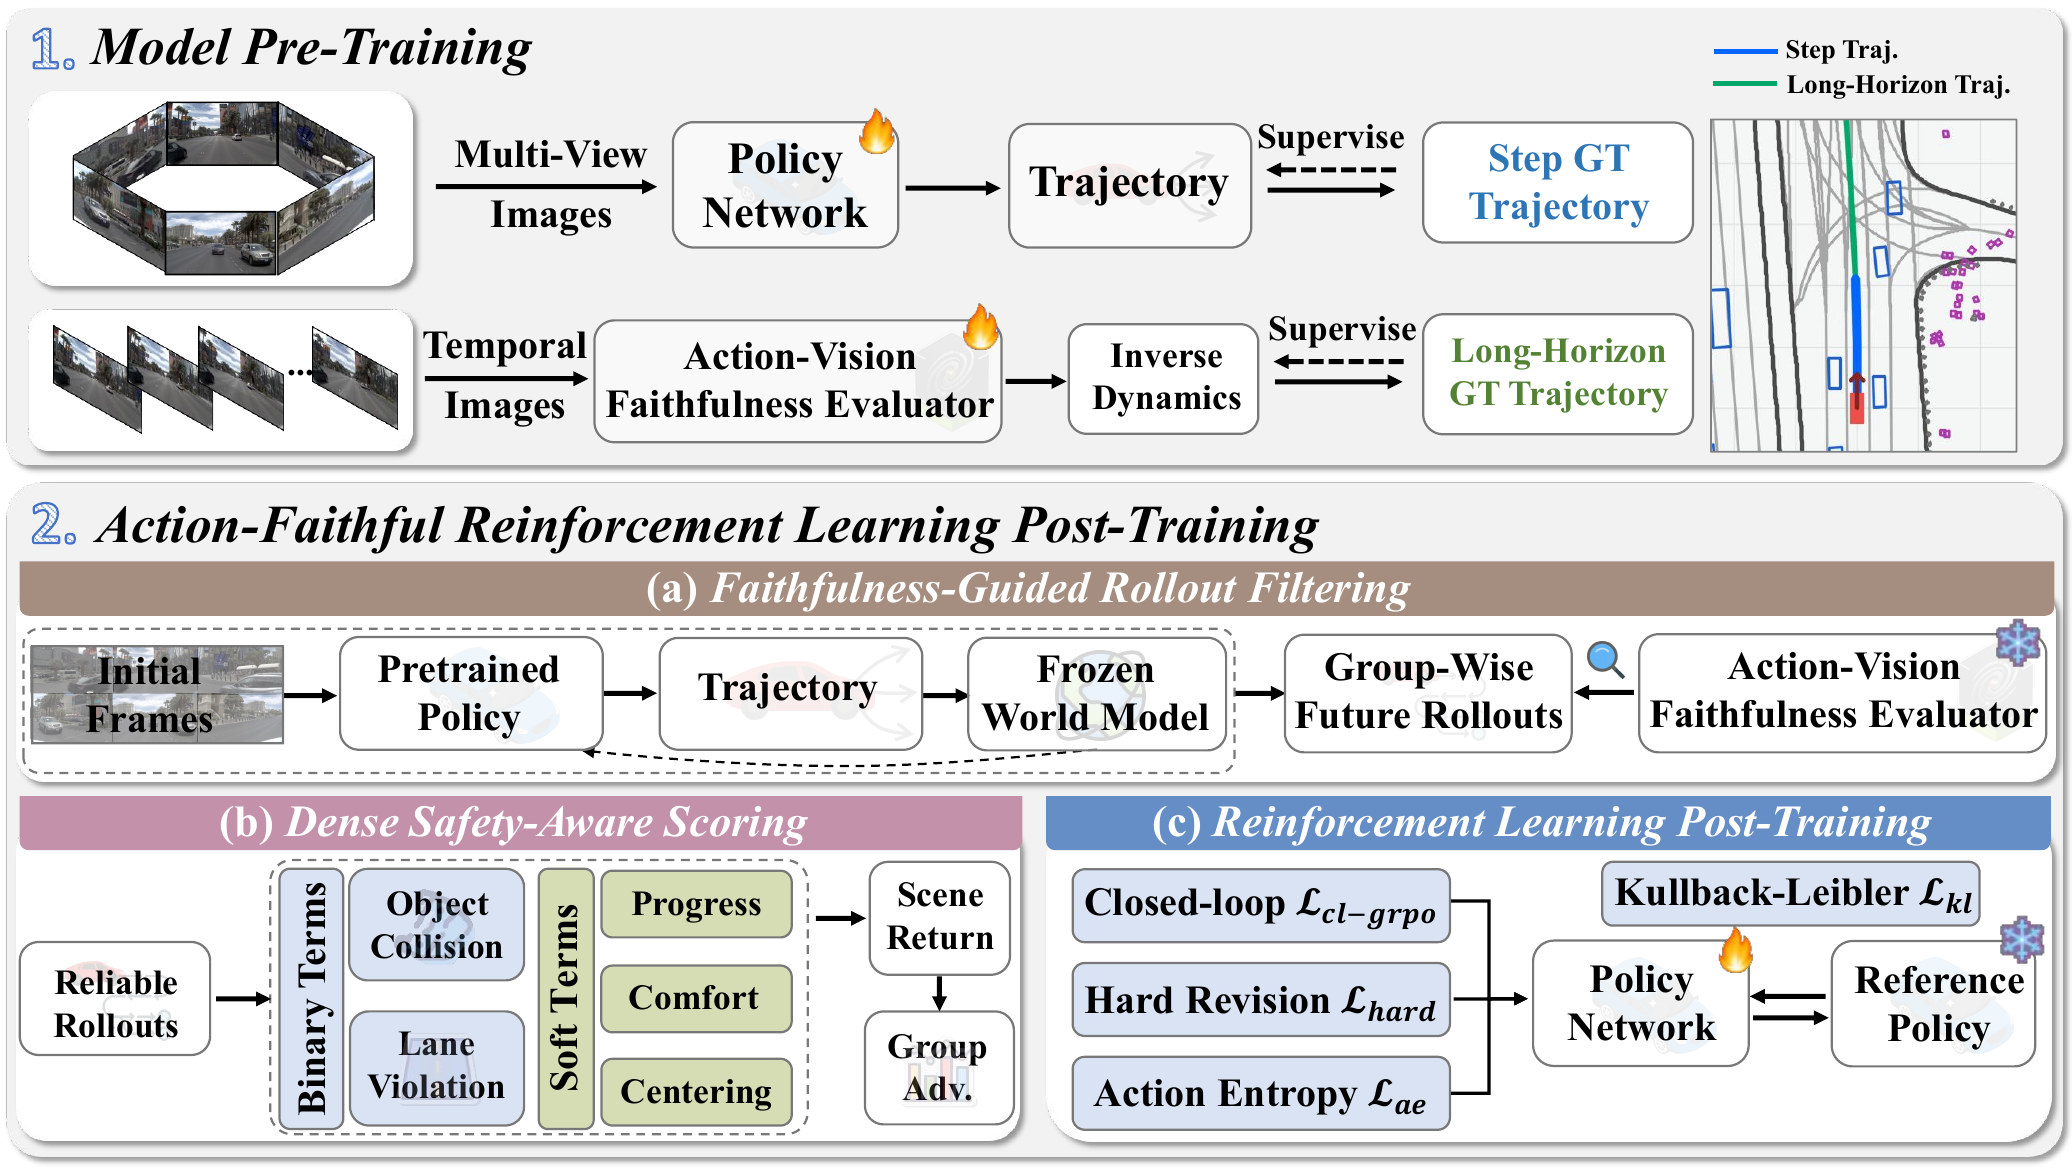
Illustration of RoXDrive. 1) Model pre-training (top): Beyond policy pre-training, we train the action-vision faithfulness evaluator (AVFE) with our geometry-aware auxiliary trajectory supervision. 2) Action-faithful RL post-training (bottom): Given the initial scene, agents iteratively interact with a frozen world model to form long-horizon scene rollouts, retaining only action-faithful ones via AVFE for dense safety-aware scoring and scene-level closed-loop RL post-training.
Quantitative Results
Open-loop collision rates (2 s) and closed-loop evaluation on 4,675 nuScenes clips (4 s, two action steps).
| Method | RL | Col. 1s ↓ | Col. 2s ↓ | Col. Avg. ↓ | Obj. Col. ↓ | Lane Viol. ↓ | Progress ↑ | Comfort ↑ | Clearance ↑ | Driving Score ↑ |
|---|---|---|---|---|---|---|---|---|---|---|
| ST-P3 | × | 0.23 | 0.62 | 0.43 | 268 | 557 | 0.397 | 0.425 | 0.387 | 0.341 |
| VAD | × | 0.07 | 0.17 | 0.12 | 820 | 824 | 0.255 | 0.681 | 0.418 | 0.271 |
| UniAD | × | 0.62 | 0.58 | 0.60 | 348 | 870 | 0.408 | 0.805 | 0.415 | 0.430 |
| CLEAR‡ | ✓ | 0.11 | 0.23 | 0.17 | — | — | — | — | — | — |
| Drive-r1‡ | ✓ | 0.02 | 0.06 | 0.04 | — | — | — | — | — | — |
| DiffusionDrive | × | 0.068 | 0.073 | 0.070 | 266 | 772 | 0.694 | 0.866 | 0.392 | 0.526 |
| DiffusionDrive + RoXDrive | ✓ | 0.029 | 0.063 | 0.046 | 189 | 562 | 0.717 | 0.883 | 0.380 | 0.588 |
| SparseDrive | × | 0.000 | 0.044 | 0.022 | 197 | 623 | 0.716 | 0.891 | 0.384 | 0.580 |
| SparseDrive + RoXDrive | ✓ | 0.000 | 0.015 | 0.007 | 173 | 598 | 0.775 | 0.922 | 0.388 | 0.622 |
Citation
@misc{lin2026roxdrive,
  title     = {RoXDrive: Closed-Loop Reinforcement Learning for End-to-End Autonomous Driving via Action-Faithful Rollouts},
  author    = {Hongbin Lin and Chaoda Zheng and Yiming Yang and Xiangyu Li and Shijia Chen and Jinhao Deng and Kangjie Chen and Dongbin Zhang and Jie Feng and Yu Zhang and Xianming Liu and Shuguang Cui and Boyang Wang and Zhen Li},
  year      = {2026}
}